Calculate LLM API cost per completed task
Build an auditable token budget that includes input, output, repeated context, cache assumptions, retries, and minimum charges.
An LLM API budget should begin with the cost of a completed task, not the advertised price of one million tokens. Count the input and output of every request needed to reach an acceptable result. Multiply those counts by the applicable rates, then account for minimum charges and any other billed services. A task that requires three attempts has a different cost from a task completed once, even when both use the same model.
This guide gives you a calculation you can reproduce in a spreadsheet. All workloads and dollar rates below are illustrative assumptions, not measured customer activity or current model offers. Use the live workload calculator to replace the example rates before planning a purchase. Eligible :free models share one monthly account allowance; the free allowance page publishes the current amount, UTC reset and wallet fallback requirements. This guide does not claim a particular model will complete your work successfully.
Start with the unit you actually want to buy
Write a one-sentence acceptance rule before measuring tokens. For a repository change, that might mean a patch that passes a named test and human review. For a document extraction, it might mean a valid record with required fields checked against the source. These rules define a completed task. Without them, an inexpensive response and a useful result can be counted as if they were the same outcome.
Keep separate identifiers for the task, each client attempt, and each provider request. One attempt may create several requests when an agent reads a file, calls a tool, and continues. Those requests belong to the same task budget. You do not need a large analytics platform for an initial evaluation: a small, access-controlled ledger can establish the relationship as long as it preserves request identities and avoids storing unnecessary sensitive prompts.
Make the basic calculation explicit
Let I be uncached input tokens, O output tokens, Pi the input price per million tokens, and Po the output price per million. The uncached token subtotal is (I × Pi + O × Po) / 1,000,000. Rates quoted per token need a different denominator. Check the unit before copying numbers between a catalog, a calculator, and your own spreadsheet.
Tokens are the processing units used by a model; they are not interchangeable with words or characters. Tokenization and request overhead can affect counts. Use actual API usage when available instead of assuming a fixed word conversion. The OpenAI explanation of token counting is useful background, but a tokenizer estimate for plain text does not establish the final bill for every provider or request shape.
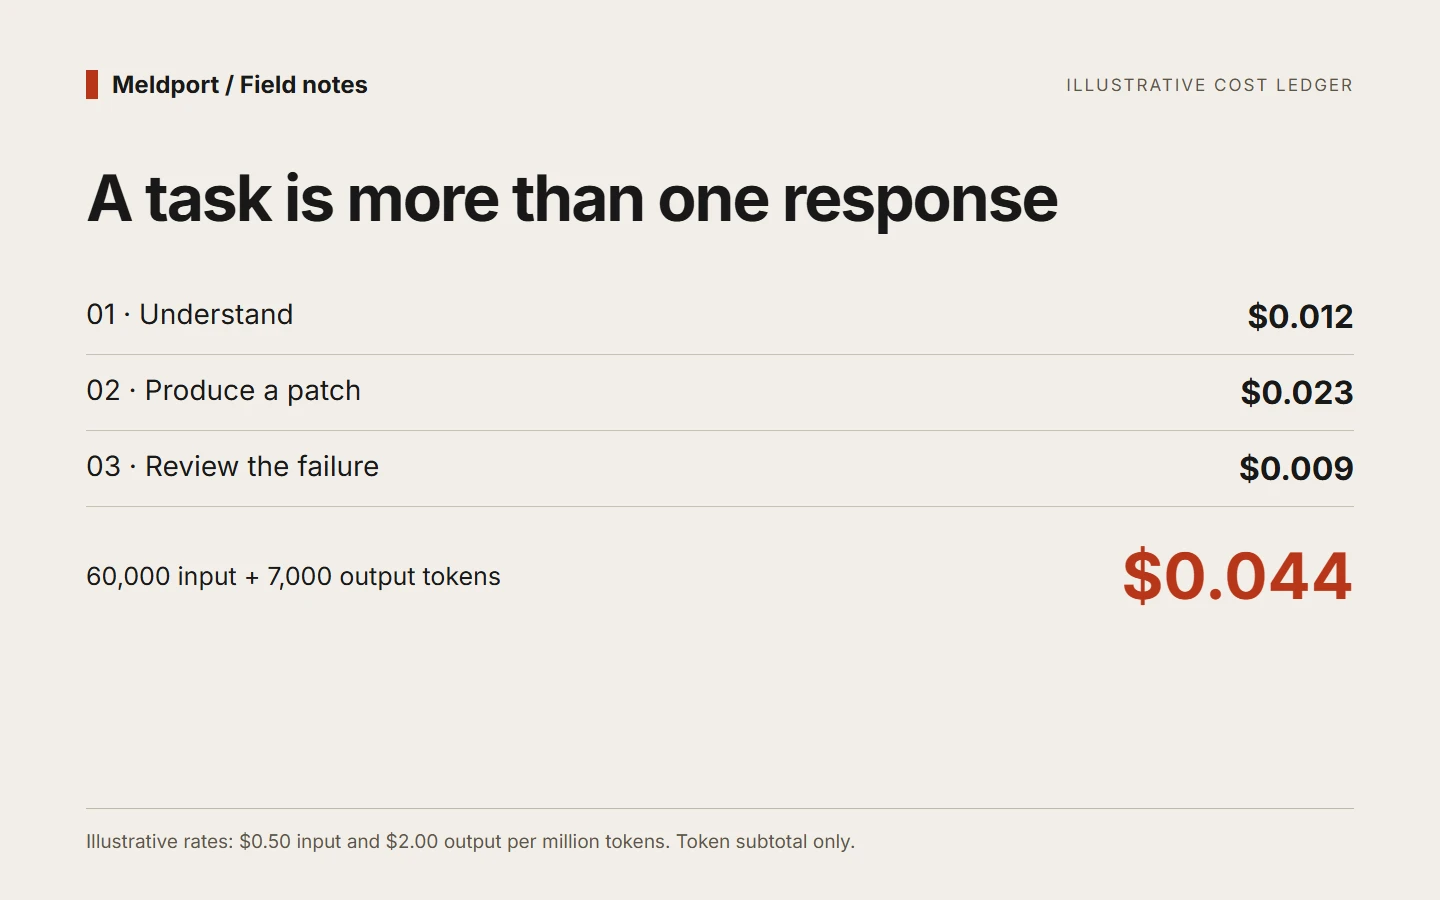
Worked example: an illustrative uncached task budget. Assumed rates are $0.50 per million input tokens and $2.00 per million output tokens.
| Request | Input tokens | Output tokens | Input cost | Output cost | Subtotal |
|---|---|---|---|---|---|
| Understand the task | 20,000 | 1,000 | $0.010 | $0.002 | $0.012 |
| Produce a patch | 30,000 | 4,000 | $0.015 | $0.008 | $0.023 |
| Review a test failure | 10,000 | 2,000 | $0.005 | $0.004 | $0.009 |
| Total | 60,000 | 7,000 | $0.030 | $0.014 | $0.044 |
Each cell can be recalculated from the formula. The total does not include a cache discount, a minimum charge, or a claim that three requests are enough for a real coding task.
Treat repeated context as part of the workload
Suppose your agent sends the same 15,000-token project summary with four requests. In an uncached scenario, the budget includes 60,000 input tokens for that summary alone. A summary that looks small in one request can therefore become a significant part of a longer loop. Count the context on each request, rather than counting the source document once and assuming later requests are free.
Record the difference between useful context and repeated context you could remove. A large file included by default may have no bearing on a small change. Conversely, stripping necessary information can cause another attempt. Evaluate both token count and task completion when changing context selection. The right comparison is the total after the change, including any additional repair requests, rather than the smaller first prompt by itself.
Model caching as a separate scenario
Do not apply a cache discount to the entire input total just because a model advertises a cache rate. Split your estimate into cached input and uncached input only when you have evidence that the particular requests qualify. Then use (uncached input × Pi + cached input × Pc + output × Po) / 1,000,000, where Pc is the applicable cached-input rate. Keep any other cache charges separate if the provider documents them.
The OpenRouter provider-routing documentation describes routing controls that can affect which upstream serves a request. Do not assume that changing gateways preserves a previous route's cache behavior. For budgeting, retain an uncached case even if your measured evaluation shows cache hits. That gives you a useful comparison when a prompt changes, a route changes, or the observed hit pattern stops repeating.
Budget assumptions that belong in the calculation. These are planning cases, not promises about billing behavior.
| Case | Assumption | What would justify it | How to report it |
|---|---|---|---|
| Uncached | All input uses the standard rate | A conservative planning choice | Base estimate |
| Observed cache | Only recorded cached input uses Pc | Request usage and applicable billing terms | Measured case |
| Retry | Another request sends additional context | A counted repair or repeat attempt | Additional subtotal |
| Minimum charge | A documented floor applies per request | Current model pricing contract | Separate adjustment |
Keep attempted requests and charges distinct
A timeout in your client does not by itself tell you whether a provider processed the request. Do not build a spreadsheet that automatically labels every timed-out attempt as free, or every attempted request as charged. Reconcile the usage record and charge record available from your gateway. Until the result is known, retain an unresolved state instead of hiding the request or inventing a charge.
For a retry, record a new request identity and connect it to the same task. This lets you calculate both the confirmed token subtotal and the cost still awaiting reconciliation. It also makes a retry policy review possible: you can see whether repeated attempts actually produced an accepted result. Avoid interpreting a successful HTTP response as proof that the content met your acceptance rule.
Expand the task budget into a monthly plan
If the illustrative task above cost $0.044 and you planned 1,000 identical tasks, the token-only estimate would be $44. This multiplication is valid only under the stated identical-workload assumption. A useful planning sheet should show task volume, the expected mix of short and long tasks, and a separate scenario for additional attempts. Do not silently describe that scenario as measured demand.
For example, if 200 of those tasks required one extra $0.023 request, the additional subtotal would be $4.60. The combined illustrative estimate becomes $48.60. This is an arithmetic sensitivity check, not a recommended safety margin or a forecast of actual failure rates. Choose your own scenarios from evidence about your application once it is available.
The minimum reconciliation ledger. The sample states describe how to organize evidence, not how Meldport guarantees settlement for every error.
| Task | Request evidence | Completion evidence | Billing evidence | Reporting state |
|---|---|---|---|---|
| Patch A | Usage counts recorded | Named test passed | Charge recorded | Confirmed task subtotal |
| Patch B | Client timeout only | No accepted patch | Charge unresolved | Pending reconciliation |
| Extraction C | Two requests recorded | Required fields checked | Both charges recorded | Confirmed two-request task |
Read usage fields before applying a cache discount
Different APIs can describe input usage differently. The Claude prompt-caching documentation separates ordinary input, cache creation, and cache reads. Its total input is the sum of those categories. A ledger that treats ordinary input as the entire prompt can undercount work; a ledger that adds a combined input total to its cache breakdown can count the same tokens twice. Read the schema of the response you actually receive, including any normalization performed by your gateway.
For a concrete spreadsheet layout, give each billing category its own token-count column and rate column. Add a final row that sums money, rather than summing all token categories and applying one blended rate. If the provider uses a cache-write premium or a storage charge, keep that adjustment visible. The practical question is whether the complete task became cheaper after all qualifying requests, rather than whether one cache-hit row looked inexpensive.
Keep the original usage record or a redacted copy alongside the calculation during evaluation. Record the response schema version and the date of the pricing evidence. When a model or adapter changes, recalculate a small sample before reusing an old spreadsheet. A plausible total is insufficient if nobody can explain how the response fields map to the charged categories.
Separate an estimate from a monthly spending control
A forecast tells you what a chosen workload might cost. It does not prevent an agent loop from continuing. Put explicit limits around the evaluation: the number of tasks, requests per task, permitted tools, maximum generated output, and the point at which a person must review unresolved work. Those controls operate at different levels. An output cap on one request cannot limit the total number of requests in a task.
Consider an illustrative ten-request task limit with a planned maximum subtotal of $0.02 per request. Multiplying the two gives a $0.20 planning envelope only if the per-request assumption includes every applicable charge. It is not a gateway-enforced dollar cap. If actual context can grow beyond the estimate, or separately billed tools are enabled, the envelope needs a different calculation. Label the control that is enforced and the number that is only an estimate.
After the first bounded sample, reconcile three totals: completed tasks in your application, requests in the usage ledger, and confirmed debits in the account. Investigate differences before expanding volume. For monthly reporting, group requests by a recorded billing timestamp and keep late settlements identifiable. This makes a month-end correction understandable without rewriting the historical task result or quietly moving an unresolved request into the next month's accepted work.
Compare two options without hiding the denominator
When comparing models, keep the acceptance rule and input task set consistent. Record how many tasks were accepted, the confirmed spend, and unresolved charges. Divide confirmed spend by accepted tasks only when the unresolved component is also disclosed. Otherwise the apparently cheaper evaluation may simply have more unknown bills or more rejected outputs.
Keep human review time and external tool charges in separate columns if they matter to your decision. This guide does not assign a dollar value to your time. A clear separation lets someone else reuse the token calculation without accepting your labor assumptions. It also prevents a token-rate comparison from becoming an unsupported claim about overall productivity.
Before buying credit, inspect the chosen model's catalog entry, follow its evidence date and minimum-charge information, and check the agent protocol requirements. Then run a small, deliberately bounded evaluation in your own environment. The calculation becomes useful when another person can reproduce every subtotal and identify which parts are observed, assumed, or still unresolved.